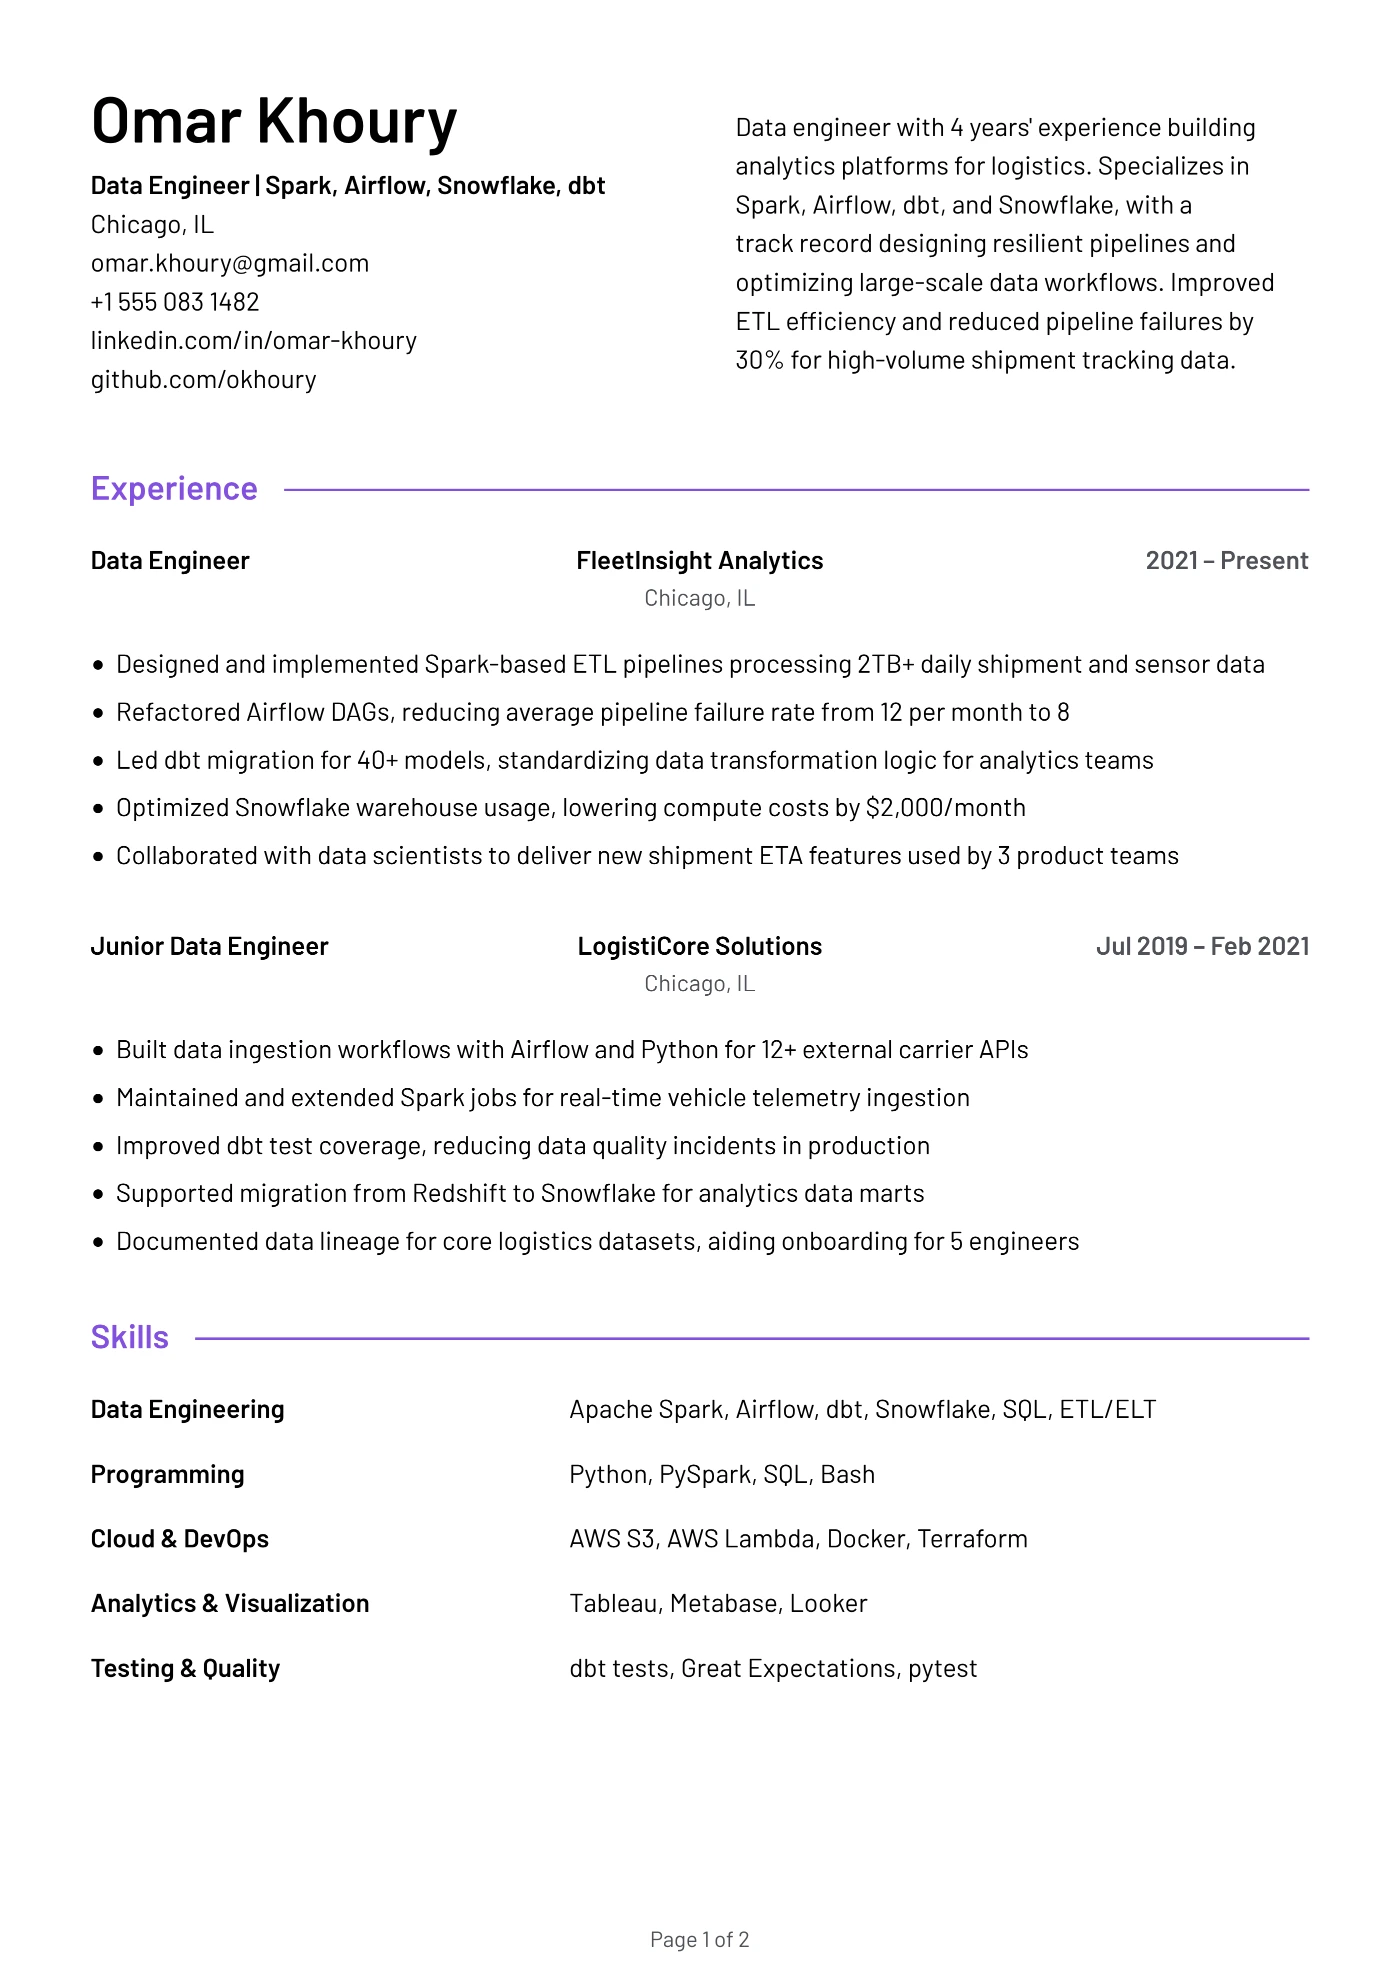
Mid-Level Data Engineer Resume Example
A mid-level data engineer resume with Spark, Airflow, dbt and Snowflake impact. Ideal for analytics platform roles in logistics or supply chain.
Why this works
- Clear scope of ownership in analytics pipelines
- Specific metrics for pipeline scale and efficiency
- Strong emphasis on stack: Spark, dbt, Snowflake
- Cloud and DevOps skills relevant to data engineering
- Education section matches technical requirements
Mid-Level Data Engineer Resume: full text
Summary
Data engineer with 4 years' experience building analytics platforms for logistics. Specializes in Spark, Airflow, dbt, and Snowflake, with a track record designing resilient pipelines and optimizing large-scale data workflows. Improved ETL efficiency and reduced pipeline failures by 30% for high-volume shipment tracking data.
Experience
Data Engineer
FleetInsight Analytics, Chicago, IL · 2021 – Present
- Designed and implemented Spark-based ETL pipelines processing 2TB+ daily shipment and sensor data
- Refactored Airflow DAGs, reducing average pipeline failure rate from 12 per month to 8
- Led dbt migration for 40+ models, standardizing data transformation logic for analytics teams
- Optimized Snowflake warehouse usage, lowering compute costs by $2,000/month
- Collaborated with data scientists to deliver new shipment ETA features used by 3 product teams
Junior Data Engineer
LogistiCore Solutions, Chicago, IL · Jul 2019 – Feb 2021
- Built data ingestion workflows with Airflow and Python for 12+ external carrier APIs
- Maintained and extended Spark jobs for real-time vehicle telemetry ingestion
- Improved dbt test coverage, reducing data quality incidents in production
- Supported migration from Redshift to Snowflake for analytics data marts
- Documented data lineage for core logistics datasets, aiding onboarding for 5 engineers
Skills
Data Engineering
Apache Spark, Airflow, dbt, Snowflake, SQL, ETL/ELT
Programming
Python, PySpark, SQL, Bash
Cloud & DevOps
AWS S3, AWS Lambda, Docker, Terraform
Analytics & Visualization
Tableau, Metabase, Looker
Testing & Quality
dbt tests, Great Expectations, pytest
Education
BSc Computer Science
DePaul University · 2015 – 2019
Data Structures & Algorithms, Databases, Distributed Systems