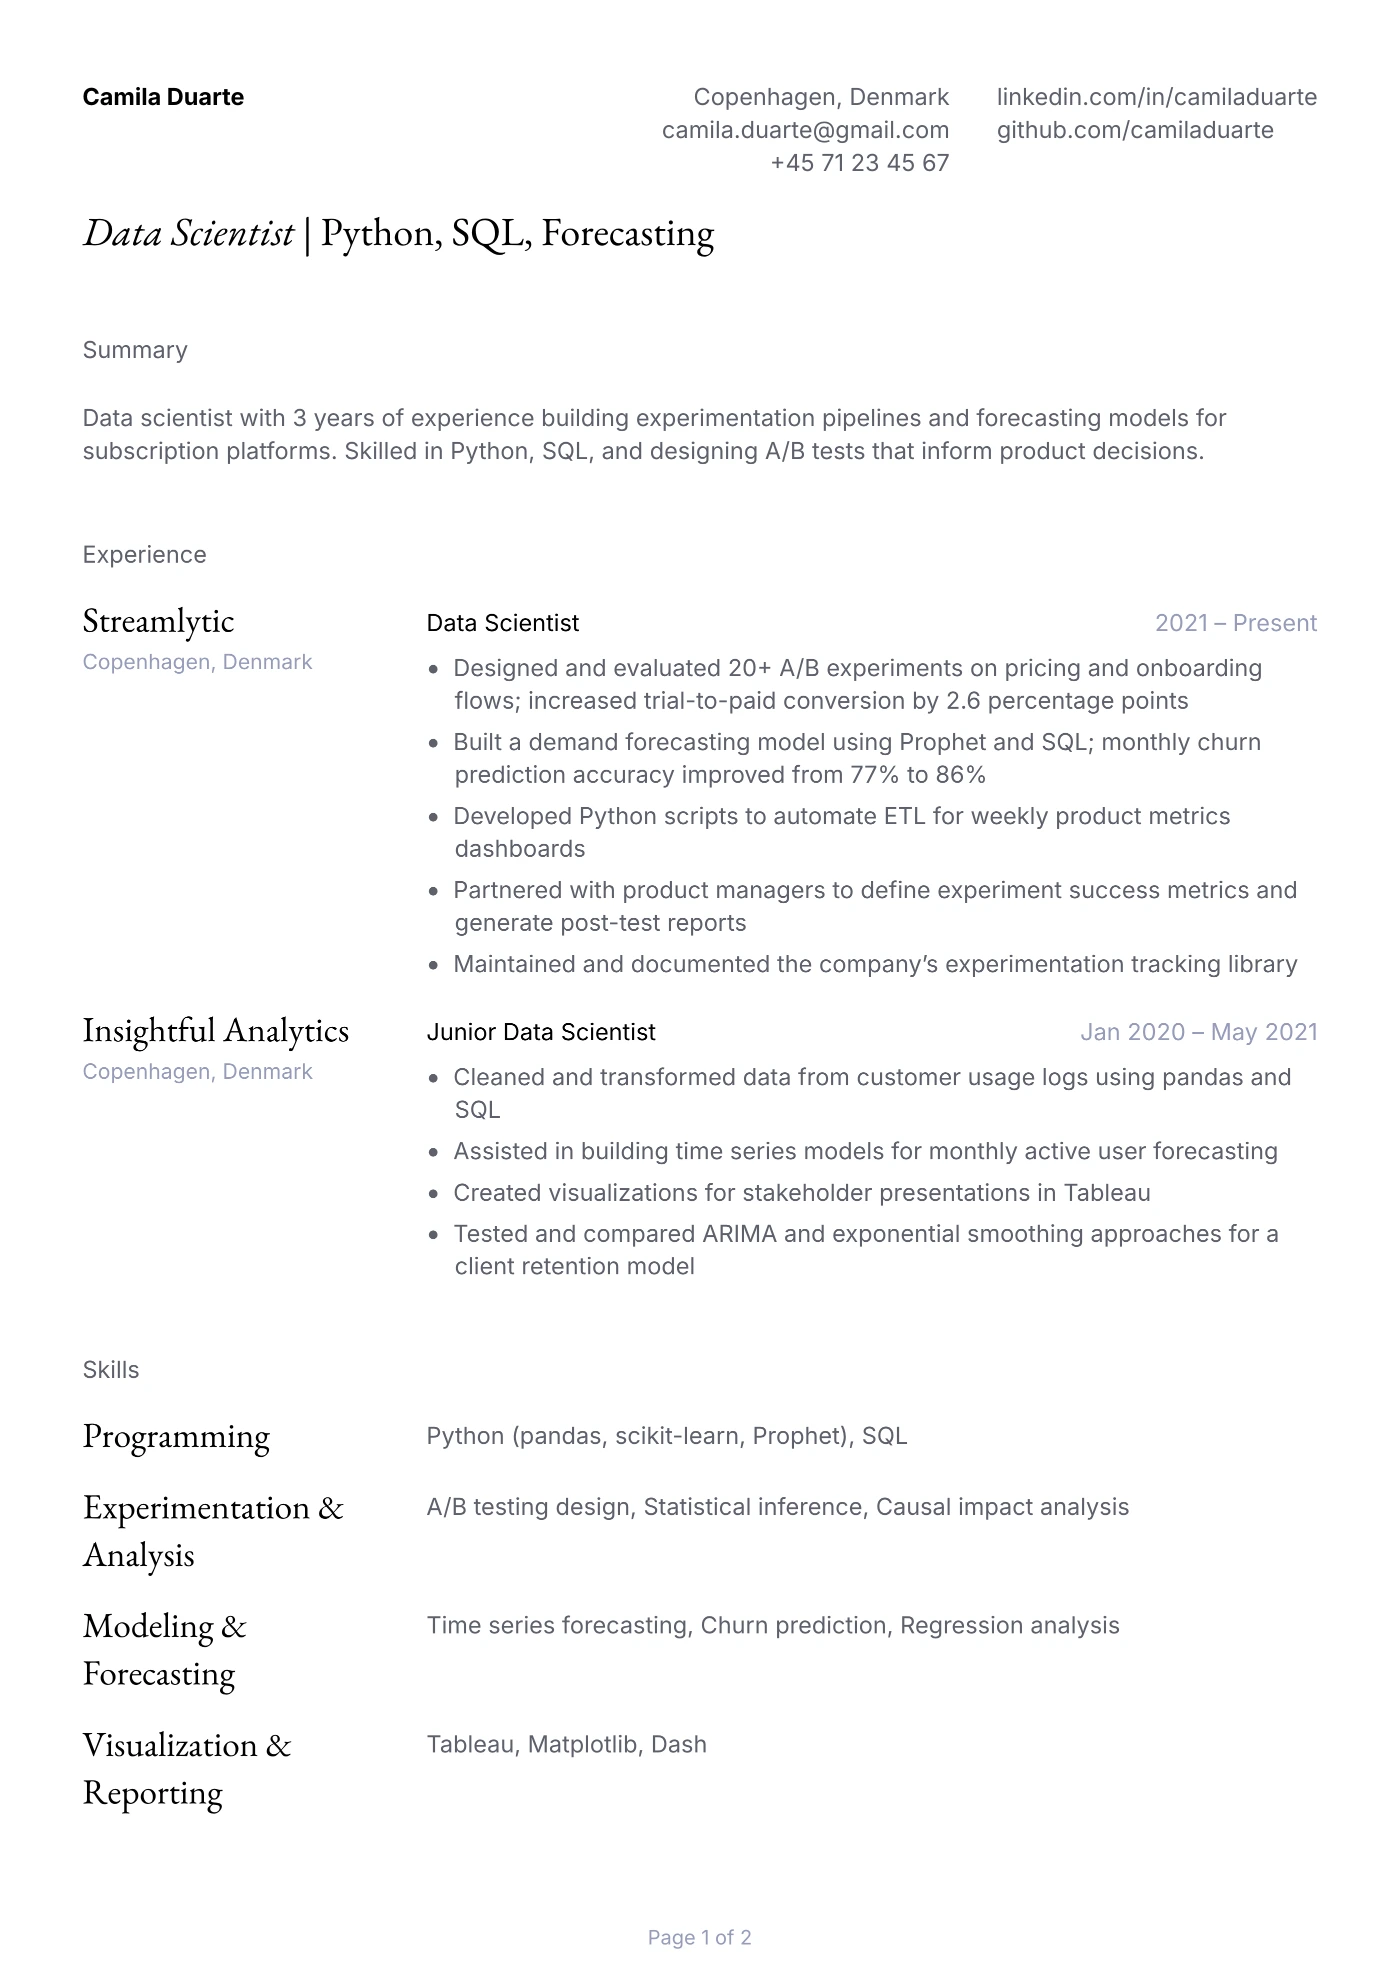
Mid-Level Data Scientist Resume Example
A mid-level data scientist resume with Python and SQL results in a subscription setting. Great for analytics and product experimentation roles.
Why this works
- Clear experiment and forecast outcomes
- Specific tools for each skill area
- Simple before-and-after conversion gains
- Relevant subscription product experience
- Education matches the analytics focus
Mid-Level Data Scientist Resume: full text
Summary
Data scientist with 3 years of experience building experimentation pipelines and forecasting models for subscription platforms. Skilled in Python, SQL, and designing A/B tests that inform product decisions.
Experience
Data Scientist
Streamlytic, Copenhagen, Denmark · Jun 2021 – Present
- Designed and evaluated 20+ A/B experiments on pricing and onboarding flows; increased trial-to-paid conversion by 2.6 percentage points
- Built a demand forecasting model using Prophet and SQL; monthly churn prediction accuracy improved from 77% to 86%
- Developed Python scripts to automate ETL for weekly product metrics dashboards
- Partnered with product managers to define experiment success metrics and generate post-test reports
- Maintained and documented the company’s experimentation tracking library
Junior Data Scientist
Insightful Analytics, Copenhagen, Denmark · Jan 2020 – May 2021
- Cleaned and transformed data from customer usage logs using pandas and SQL
- Assisted in building time series models for monthly active user forecasting
- Created visualizations for stakeholder presentations in Tableau
- Tested and compared ARIMA and exponential smoothing approaches for a client retention model
Skills
Programming
Python (pandas, scikit-learn, Prophet), SQL
Experimentation & Analysis
A/B testing design, Statistical inference, Causal impact analysis
Modeling & Forecasting
Time series forecasting, Churn prediction, Regression analysis
Visualization & Reporting
Tableau, Matplotlib, Dash
Education
MSc Data Science
IT University of Copenhagen · Sep 2018 – Jun 2020
Thesis on churn prediction in digital subscriptions
BSc Statistics
Universidad Nacional de Córdoba · Mar 2014 – Dec 2018
How to write a mid-level data scientist resume
Show the scope and direct impact of your work with concrete examples. At mid-level, hiring managers expect you to have owned analysis pipelines, delivered models that improved a business metric, and collaborated with product or analytics teams. List achievements with clear numbers and describe the technical context.
Structure your resume around practical results: what data you worked with, which models or experiments you built, and how your work changed a product or decision. Highlight hands-on experience with Python, SQL, and tools like Tableau or Prophet. Keep sections concise and relevant to data science in production.
What skills should a data scientist put on a resume?
List technical skills that match real business problems you have solved. Show your stack depth—Python libraries, SQL for pipeline work, and the statistical methods behind the models. Call out experimentation frameworks and reporting tools you have used to deliver findings.
- Programming: Python (pandas, scikit-learn, Prophet), SQL
- Experimentation: A/B test design, causal inference, experiment analysis
- Modeling: Time series forecasting, churn and retention modeling, regression
- ETL and Data Pipelines: Automated metric reporting, data cleaning workflows
- Visualization: Tableau, Matplotlib, Dash dashboards
Data scientist resume bullet point examples
Bullet points should make clear what you built, which tools you used, and the business value or metric moved. Where possible, give before/after values or the scale of your work.
- Automated cohort retention reporting in Python and SQL; manual analysis time dropped from 2 days to under 2 hours per cycle
- Shipped a time series anomaly detector for daily user activity; flagged 95% of known incidents in test data
- Moved product metrics dashboards from Excel to Tableau; 12 teams now access live reporting
- Tested two onboarding flows on 15,000 users; activation rate rose from 45% to 52%
- Owned the weekly experiment review process for product managers and analysts
Common mistakes on data scientist resumes
Avoid vague claims, generic tool lists, and overfocusing on coursework or side projects. Show your real production impact, not just academic knowledge.
- Listing all Python libraries used instead of focusing on those applied to shipped work
- Describing models without stating the business metric they affected
- Leaving out stakeholders—omit who used your analysis and why
- Padding with coursework when you already have on-the-job experience
Frequently asked questions
How long should a mid-level data scientist resume be?
One page is enough for most mid-level data scientists with 2–4 years of experience. Focus on work that used your main technical stack and changed business metrics. Leave out unrelated jobs and coursework unless it's directly relevant.
Should I include side projects or Kaggle competitions?
Include side projects or competitions only if they use the same stack and show production-level modeling or analysis. Briefly describe the dataset size, methods, and what you learned; avoid listing every hackathon unless results are significant.
How can I show leadership or ownership at mid-level?
Show ownership by naming processes or deliverables you managed, like experiment reviews, reporting pipelines, or model deployments. Mention when you partnered with product managers or analysts, or supported decision-making with your work.
Which data science keywords matter most for product analytics roles?
Keywords like A/B testing, churn modeling, time series forecasting, Python (pandas, scikit-learn), SQL, and Tableau are core for product analytics data scientist roles. Also mention experiment design, causal inference, and automated reporting if you have hands-on experience.