Senior Data Engineer Resume Example
A senior data engineer resume example with deep streaming and data platform impact. Ideal for adtech or high-scale analytics roles.
Why this works
- Streaming platform leadership with real numbers
- Clear career progression and team impact
- Bullets specify technologies and business outcomes
- Metrics on latency, scale, and adoption
- Grouped skills highlight technical depth
Senior Data Engineer Resume: full text
Summary
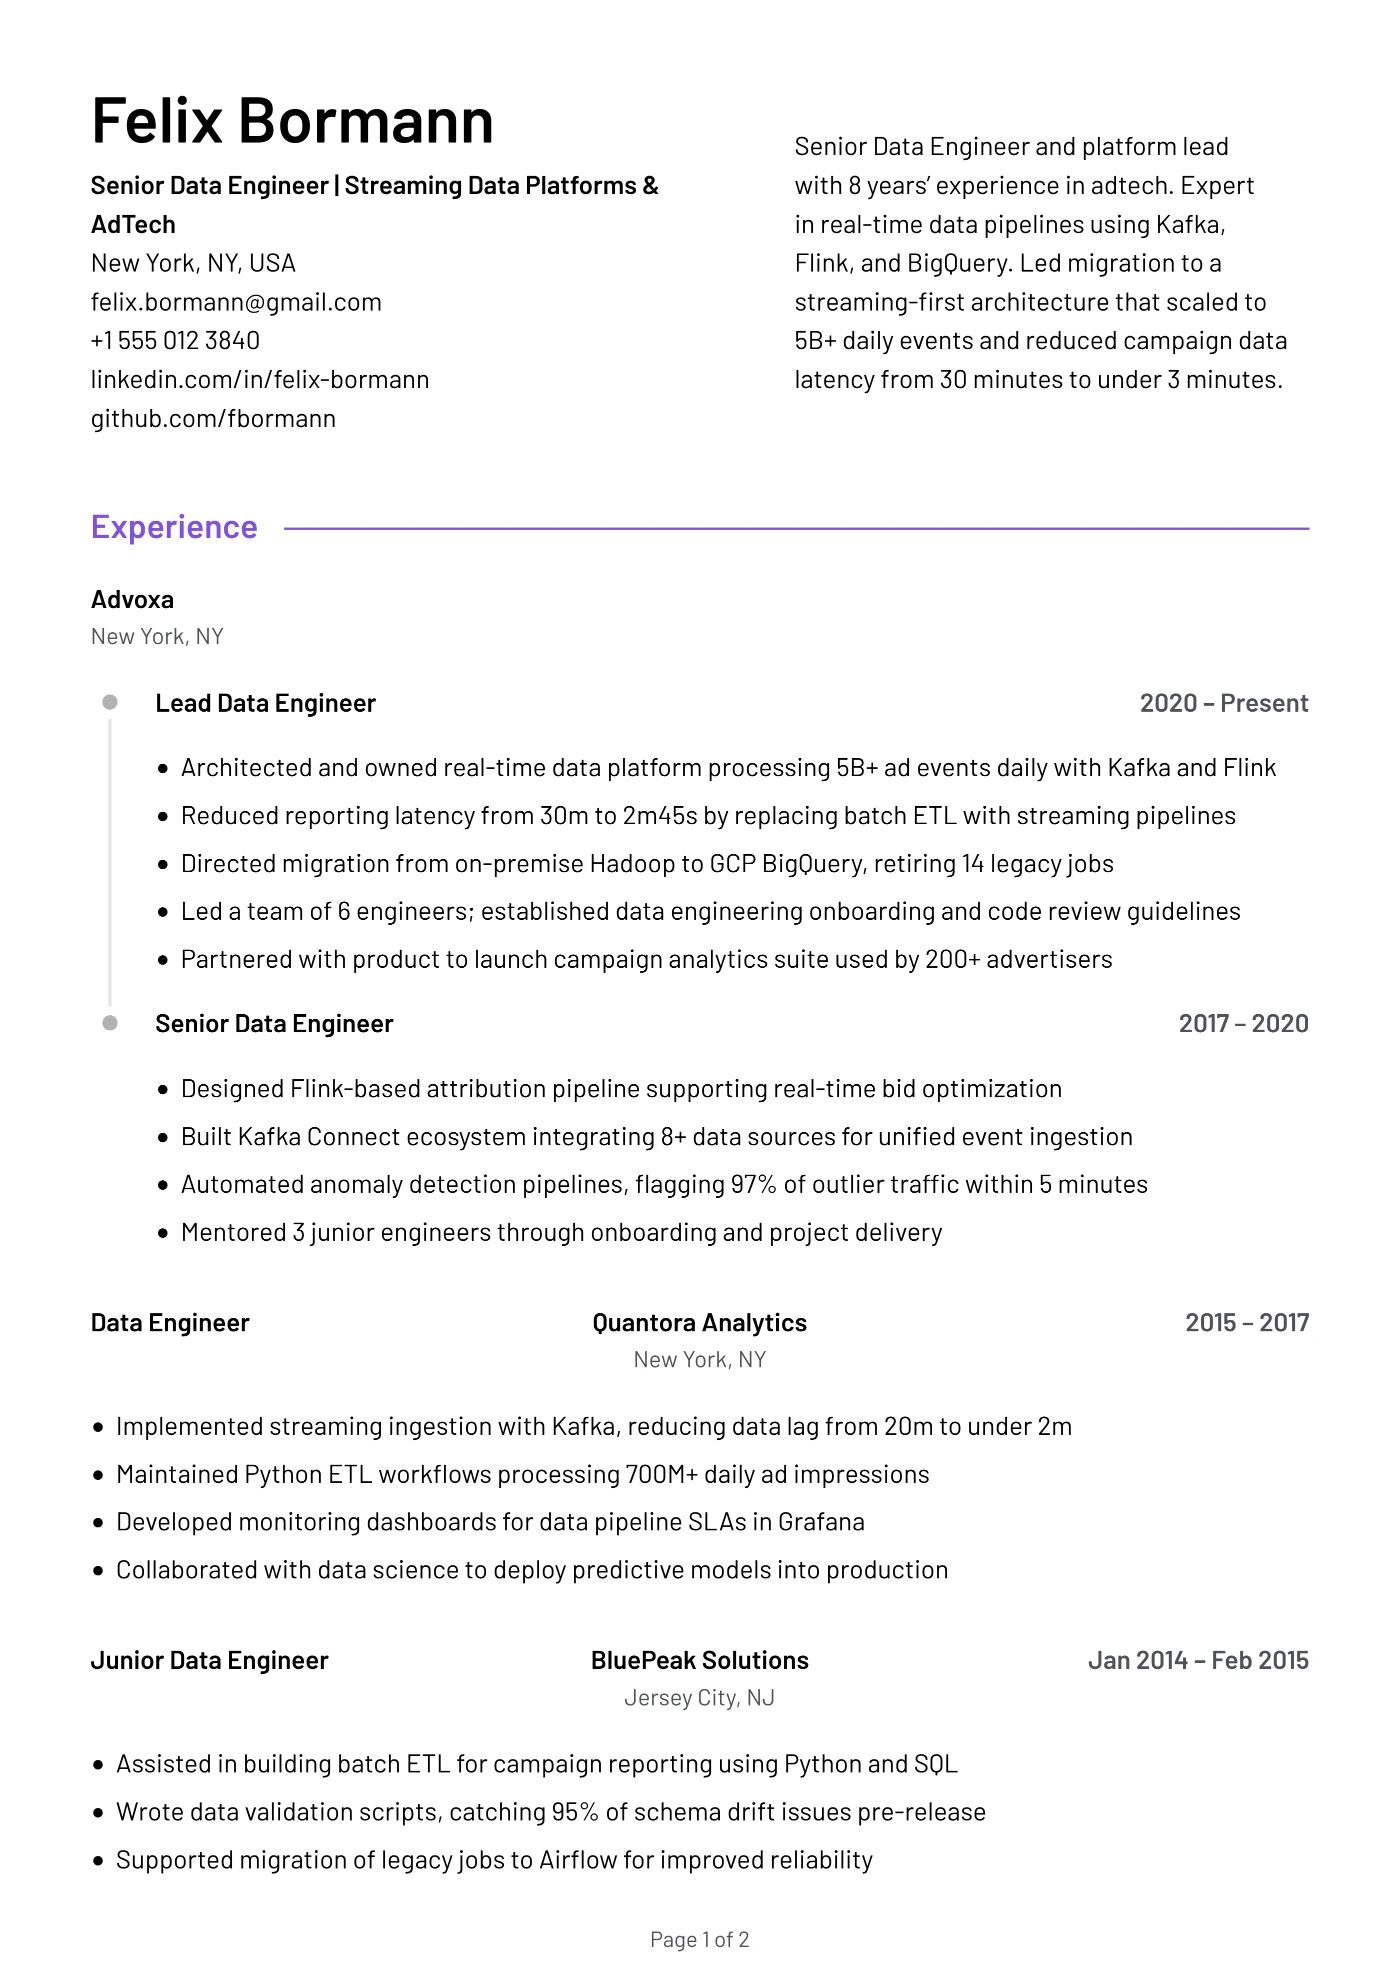
Senior Data Engineer and platform lead with 8 years’ experience in adtech. Expert in real-time data pipelines using Kafka, Flink, and BigQuery. Led migration to a streaming-first architecture that scaled to 5B+ daily events and reduced campaign data latency from 30 minutes to under 3 minutes.
Experience
Lead Data Engineer
Advoxa, New York, NY · 2020 – Present
- Architected and owned real-time data platform processing 5B+ ad events daily with Kafka and Flink
- Reduced reporting latency from 30m to 2m45s by replacing batch ETL with streaming pipelines
- Directed migration from on-premise Hadoop to GCP BigQuery, retiring 14 legacy jobs
- Led a team of 6 engineers; established data engineering onboarding and code review guidelines
- Partnered with product to launch campaign analytics suite used by 200+ advertisers
Senior Data Engineer
Advoxa, New York, NY · 2017 – 2020
- Designed Flink-based attribution pipeline supporting real-time bid optimization
- Built Kafka Connect ecosystem integrating 8+ data sources for unified event ingestion
- Automated anomaly detection pipelines, flagging 97% of outlier traffic within 5 minutes
- Mentored 3 junior engineers through onboarding and project delivery
Data Engineer
Quantora Analytics, New York, NY · 2015 – 2017
- Implemented streaming ingestion with Kafka, reducing data lag from 20m to under 2m
- Maintained Python ETL workflows processing 700M+ daily ad impressions
- Developed monitoring dashboards for data pipeline SLAs in Grafana
- Collaborated with data science to deploy predictive models into production
Junior Data Engineer
BluePeak Solutions, Jersey City, NJ · Jan 2014 – Feb 2015
- Assisted in building batch ETL for campaign reporting using Python and SQL
- Wrote data validation scripts, catching 95% of schema drift issues pre-release
- Supported migration of legacy jobs to Airflow for improved reliability
Skills
Data Engineering
Apache Kafka, Apache Flink, Apache Beam, BigQuery, Airflow, Kafka Connect
Programming
Python (PySpark, data tooling), Java, SQL
Cloud & DevOps
GCP (BigQuery, Dataflow, Pub/Sub), Terraform, Docker, Kubernetes
Data Modeling & Analytics
Star/Snowflake schema design, Looker, dbt, data quality monitoring
Monitoring & Testing
Prometheus, Grafana, pytest, Great Expectations
Education
BSc Computer Science
Technical University of Munich · 2010 – 2013
Thesis: "Stream Processing Architectures for Real-Time Analytics"
How to write a senior data engineer resume
Hiring managers for senior data engineer roles expect to see a track record of architecting and scaling robust data platforms, particularly with modern streaming and cloud technologies. Your resume should emphasize leadership in migrations, low-latency pipelines, and the adoption of new frameworks that support business-critical analytics at scale.
Structure your resume to foreground technical impact: start with a concise summary, followed by clearly segmented experience that highlights ownership of core systems, team leadership, and tangible improvements (such as latency reductions or volume handled). Quantify your results and focus on the complexity and scale of your work.
What skills should a data engineer put on a resume?
A data engineer resume should reflect mastery of distributed data processing, programming, cloud infrastructure, and operational excellence. Group your skills to show breadth and depth across the data stack, with emphasis on relevant tools and platforms.
- Data pipeline architecture: Apache Kafka, Apache Flink, Apache Beam, Kafka Connect
- Cloud data platforms: GCP (BigQuery, Dataflow, Pub/Sub), Terraform
- Programming & automation: Python (PySpark, data tooling), Java, SQL, Airflow
- Data modeling & analytics: Star/Snowflake schema, dbt, Looker, data quality monitoring
- Monitoring & reliability: Prometheus, Grafana, pytest, Great Expectations
- Containerization and orchestration: Docker, Kubernetes
Data engineer resume bullet point examples
Use bullet points that tie technical work to measurable business outcomes, showing how you improved system performance or enabled new capabilities. Vary your evidence—give before/after metrics, absolute scales, and examples of systems you built or modernized.
- Migrated attribution pipelines to Flink, reducing end-to-end event processing time from 900ms to 350ms for live campaign metrics.
- Designed and launched a unified data ingestion framework supporting 12 third-party sources, scaling from 1B to 4B daily events in 18 months.
- Automated alerting on data quality checks, catching 99% of critical schema violations before downstream impact.
- Led deprecation of on-premise batch ETL workflows, delivering a fully cloud-native analytics stack for all new ad products.
- Partnered with analytics to roll out Looker dashboards, enabling real-time insights for 250+ internal and external stakeholders.
Common mistakes on data engineer resumes
Many senior data engineer resumes miss the mark by being too vague or overly focused on tools without context. Avoid generic descriptions and be explicit about your leadership, scale, and technical decisions.
- Listing technologies without describing how you used them—always connect tools to project outcomes.
- Omitting scale or impact—quantify data volumes, latency improvements, and business results.
- Ignoring leadership or mentorship—highlight onboarding, code reviews, or team enablement.
- Focusing only on pipeline construction—show contributions to reliability, monitoring, and data quality.
Frequently asked questions
How long should a senior data engineer resume be?
A two-page resume is appropriate for a senior data engineer, especially when detailing complex projects, leadership, and technology migrations. Prioritize recent and relevant experience, quantifying impact and scale. Trim early-career roles to essentials and avoid redundant skill listings.
Should I list side projects or open-source contributions as a senior data engineer?
Include side projects or open-source work only if they use technologies relevant to the stack (Kafka, Flink, BigQuery, etc.) or demonstrate architectural and leadership skills. Highlight contributions that show production-level quality, scalability, or community impact—not just personal learning.
How can I show leadership experience as a data engineer without a manager title?
Demonstrate leadership through examples of mentoring, onboarding, code review processes, or leading migrations and technical initiatives. Describe how you set standards, enabled teammates, or drove platform decisions, giving concrete outcomes or improvements enabled by your guidance.
Which keywords matter most for a senior data engineer applying to adtech companies?
Critical keywords include Kafka, Flink, BigQuery, real-time pipelines, streaming, data modeling, GCP, Airflow, and large-scale event processing. Emphasize experience with low-latency data flows, cloud migrations, and supporting analytics for high-traffic environments—these signal fit for adtech platforms.